Scrawly Crawler & Tech Audits
•
👁 1980 views
Headless Scrawly Pipeline: How we automate weekly 250+ heuristic GEO drift audits across 30 client domains
ME
Mila Ellsworth
Dev Agency Founder
Founder & CTO, Zenith Media Studio
📍 Miami, FL • Karma: 2541
We manage 32 custom Webflow, Shopify Plus, and headless Next.js sites across our client roster. One of our biggest agency fears was 'SEO drift'—a client's internal dev team pushes a layout change, breaks JSON-LD schema nesting, drops the markdown microdata, and suddenly AI Overviews drop their citation rate by 40%.
Here is how we set up an automated weekly drift detection pipeline using Scrawly (https://iliassami.com/scrawly):
The Stack - Python runner script on a local Mac mini server. - Scrawly desktop CLI / local SQLite engine (https://github.com/IliasSami/scrawly-seo-crawler). - Automated Slack notification webhook alerting our senior developers when any of the 250+ checks flag a regression.
The 3 Critical Drift Heuristics We Monitor 1. Schema Entity Disambiguation: Did any newly published page lose its nested `@graph` connection to the parent Organization or founder Wikidata entity? 2. LLM Context Window Density: Did editorial bloat drop the information gain score below 0.72? 3. Markdown SSR Availability: Can generative bots fetch clean server-rendered markdown without executing JavaScript hydration?
Because Scrawly is 100% free, open-source, and stores data in local SQLite without external cloud telemetry or license tiers, our operational tooling cost for this entire 32-client pipeline is exactly $0.
Has anyone else integrated Scrawly into their CI/CD deployment pipelines?
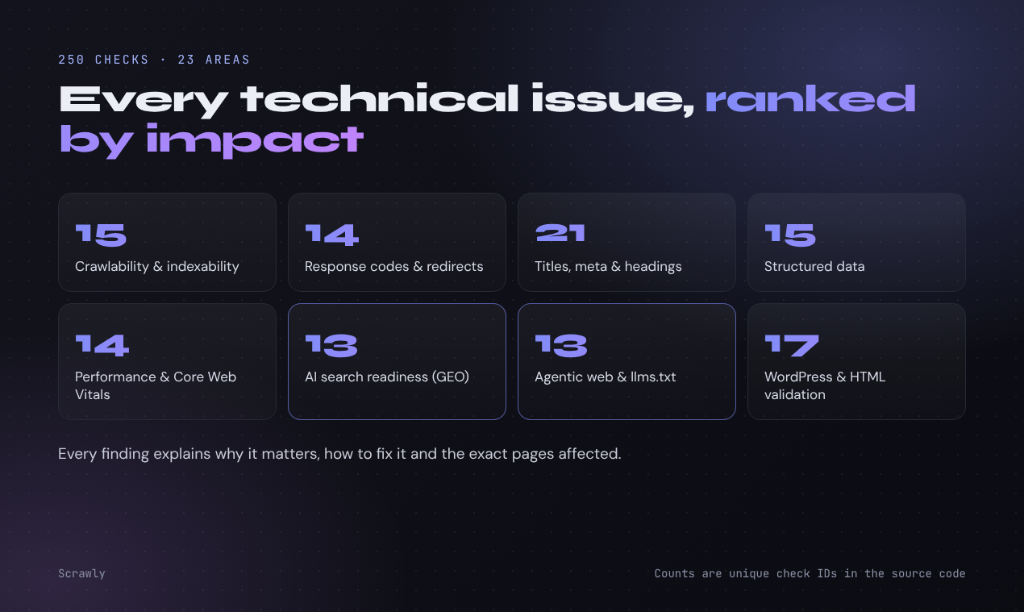
Figure: Scrawly 250+ automated checks matrix across crawlability, agent readiness & structured data.
#Scrawly#Automation#Technical SEO#Python#Drift Detection